- Neon Skyline Silhouette: "SPACEX: CHASING THE UNIVERSE" rendered in glowing neon type over a towering cyberpunk cityscape silhouette that fades into a starfield, with rain-slicked streets reflecting the neon glow to tie the urban cyberpunk setting to the space theme (the brief gives no platform, release date, or tagline, so none are included).
- Circuit-Universe Fusion: "SPACEX: CHASING THE UNIVERSE" set in a sharp, tech-style typeface where the letterforms dissolve into circuit-board patterns on one side and cosmic nebula textures on the other, visually merging cyberpunk tech with the…
Compare AI models on your own tasks
Paste your test cases, pick the models, and run them all at once. LLMCompare shows how well each model handles your task, next to what it costs and how long it takes.
- Judged by your standardoutputs are checked against what your task needs, not spec sheets
- No codeeverything runs in the browser
- No API keyswe call the models and charge credits
A real model comparison report
This report comes from an evaluation we ran on 19 October 2026: 3 test cases, 3 models, 1 run per test case. Every number can be checked in the full report.
C (GPT-5.6 Terra) passed 100% of judged outputs, 67 points above A, at 30% of A's cost per call.
- A (Claude Sonnet 5) passed 33% of judged outputs, at $0.0083 per call.
- B (Gemini 3.7 Flash) passed 67% of judged outputs, 34 points above A, at 65% of A's cost per call.
- B (Gemini 3.7 Flash) averaged 11.1 s per call, against 10.3 s for A.
- C (GPT-5.6 Terra) averaged 3.3 s per call, against 10.3 s for A.
Each test case ran once, so the quality result is an observation, not a rate.
The run has 3 test cases. With fewer than 10, read the result as a reference only.
Test conditions
- Test cases
- 3
- Models
- Claude Sonnet 5, Gemini 3.7 Flash, GPT-5.6 Terra
- Runs per test case
- 1
- Prompt caching
- On
- Run date
- 19 October 2026
- Prices checked
- 30 September 2026
- Quality judged by
- Model judge (GPT-6 Luna)
- Measured from
- Tencent Cloud (prod)
Model
Outputs passed by the model judge
Average response time
Cost per call
Claude Sonnet 5
1of 3
10.3s
$0.0083
Gemini 3.7 Flash
2of 3
11.1s
$0.0054
GPT-5.6 Terra
3of 3Highest
3.3sLowest
$0.0025Lowest
How it is judgedA judge model scored every output against criteria written for this task.
How it is measuredFrom our server (Tencent Cloud (prod)), from sending the request to receiving the complete output.
How it is calculatedThe provider's published price multiplied by the usage it reported. Reasoning tokens are included.
Result for every test case
Verdict shown: Model judge (GPT-6 Luna).
| Test case | Claude Sonnet 5Anthropic | Gemini 3.7 FlashGoogle | GPT-5.6 TerraOpenAI |
|---|---|---|---|
| 1Poster for a cyberpunk game called SPACEX: Chasing the Universe. | Passed11.8 s | Passed8.8 s | Passed2.8 s |
| 2Hiring poster for Yujian, a counselling app start-up looking for a senior back-end engineer. It should feel professional and reliable, but not cold like a big corporation. It must show the salary (30K to 55K a month), that the role is remote first, and that applications close on the 15th of next month. | Failed8.5 s | Passed13.9 s | Passed4.4 s |
| 3Pop-up exhibition for Zero Yoko, an independent perfume brand, held in a traditional machiya townhouse in Kyoto. Theme: the memory of scent. It runs for three days. Avoid the usual Japanese minimalist look. | Failed10.5 s | Failed10.6 s | Passed2.7 s |
Quality against cost
Higher and further left is better.
- Nothing else is both better and cheaper
| Contestant | Outputs passed by the model judge | Cost per call | Average response time | On the frontier |
|---|---|---|---|---|
| A · Claude Sonnet 5 | 33% | $0.0083 | 10.3 s | No |
| B · Gemini 3.7 Flash | 67% | $0.0054 | 11.1 s | No |
| C · GPT-5.6 Terra | 100% | $0.0025 | 3.3 s | Yes |
Cost is the average for one call in this run. A gold ring marks a model that no other model beats on both quality and cost.
Outputs side by side
What each model returned for test case 1.
Test casePoster for a cyberpunk game called SPACEX: Chasing the Universe.
- Neon Cybernetic: "SPACEX: Chasing the Universe", featuring high-contrast neon lighting against dark cosmic space, though specific character imagery, release dates, and platforms are missing from the brief.
- Terminal Glitch Minimal: "SPACEX: Chasing the Universe", focusing on bold, distorted futuristic typography over wireframe geometric grids, noting that key marketing assets like release information, credits, and developer details are missing from the brief.
- Tech-Noir HUD: "SPACEX: Chasing the Universe", framing deep space through a gritty, layered holographic cockpit interface,…
- Neon Pursuit: “SPACEX: Chasing the Universe” — A high-contrast cyberpunk poster with electric neon typography, a futuristic cityscape, and a lone figure moving toward a glowing cosmic horizon.
- Cosmic Glitch: “SPACEX: Chasing the Universe” — The title fractures through digital glitch effects over a deep-space backdrop, blending starfields with sharp holographic interface elements.
- Chrome Ascension: “SPACEX: Chasing the Universe” — Metallic, reflective lettering rises above a dark futuristic skyline, with radiant celestial light cutting through atmospheric haze.
Shortened here. The full report has the complete output.
This report comes from an evaluation we ran on 19 October 2026: 3 test cases, 3 models, 1 run per test case. Every number can be checked in the full report.
B (Nano Banana 2 (Gemini 3.1 Flash Image)) passed 67% of judged outputs, 33 points below A, at 5.3 times A's cost per call.
- A (GPT Image 2.5 Sunburst) passed 100% of judged outputs, at $0.013 per call.
- C (Seedream 5.0 Pro) passed 67% of judged outputs, 33 points below A, at 3.5 times A's cost per call.
- B (Nano Banana 2 (Gemini 3.1 Flash Image)) averaged 8.9 s per call, against 17.0 s for A.
- C (Seedream 5.0 Pro) averaged 1 min 9 s per call, against 17.0 s for A.
Each test case ran once, so the quality result is an observation, not a rate.
The run has 3 test cases. With fewer than 10, read the result as a reference only.
Test conditions
- Test cases
- 3
- Models
- GPT Image 2.5 Sunburst, Nano Banana 2 (Gemini 3.1 Flash Image), Seedream 5.0 Pro
- Runs per test case
- 1
- Prompt caching
- Off
- Run date
- 19 October 2026
- Prices checked
- 30 September 2026
- Quality judged by
- Model judge (Gemini 3.7 Flash)
- Measured from
- Tencent Cloud (prod)
Model
Outputs passed by the model judge
Average response time
Cost per call
GPT Image 2.5 Sunburst
3of 3Highest
17.0s
$0.0128Lowest
Nano Banana 2 (Gemini 3.1 Flash Image)
2of 3
8.9sLowest
$0.0672
Seedream 5.0 Pro
2of 3
1m 9 s
$0.045
How it is judgedA judge model scored every output against criteria written for this task.
How it is measuredFrom our server (Tencent Cloud (prod)), from sending the request to receiving the complete output.
How it is calculatedThe provider's published price multiplied by the usage it reported. Reasoning tokens are included.
Result for every test case
Verdict shown: Model judge (Gemini 3.7 Flash).
| Test case | GPT Image 2.5 SunburstOpenAI | Nano Banana 2 (Gemini 3.1 Flash Image)Google | Seedream 5.0 ProByteDance Seed |
|---|---|---|---|
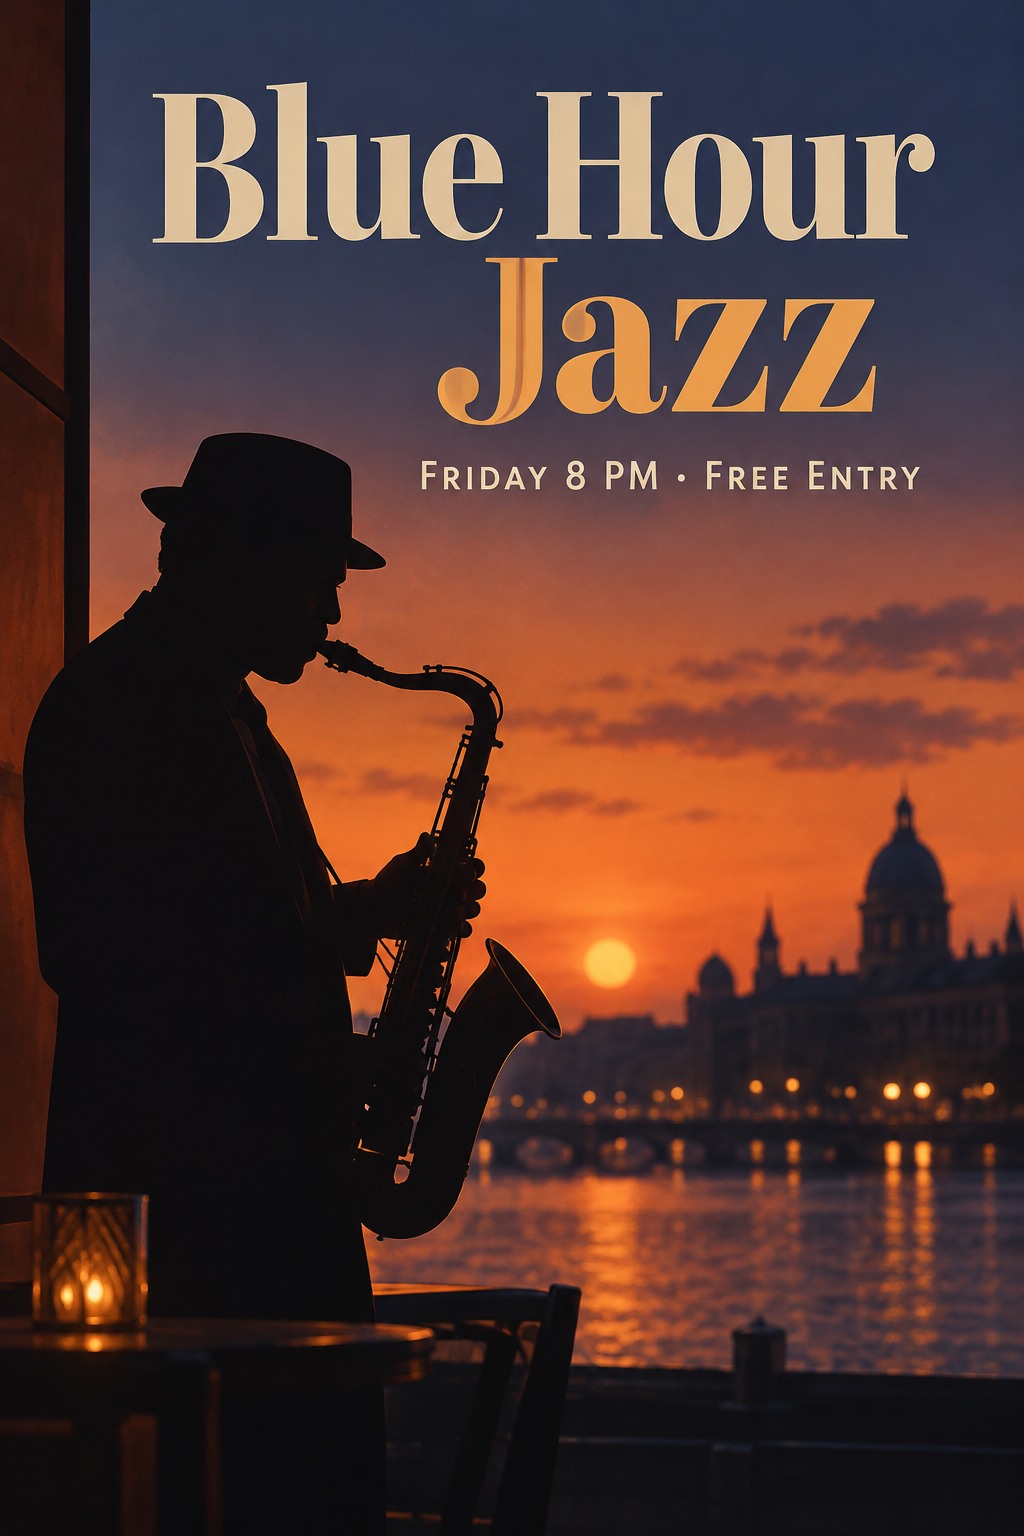
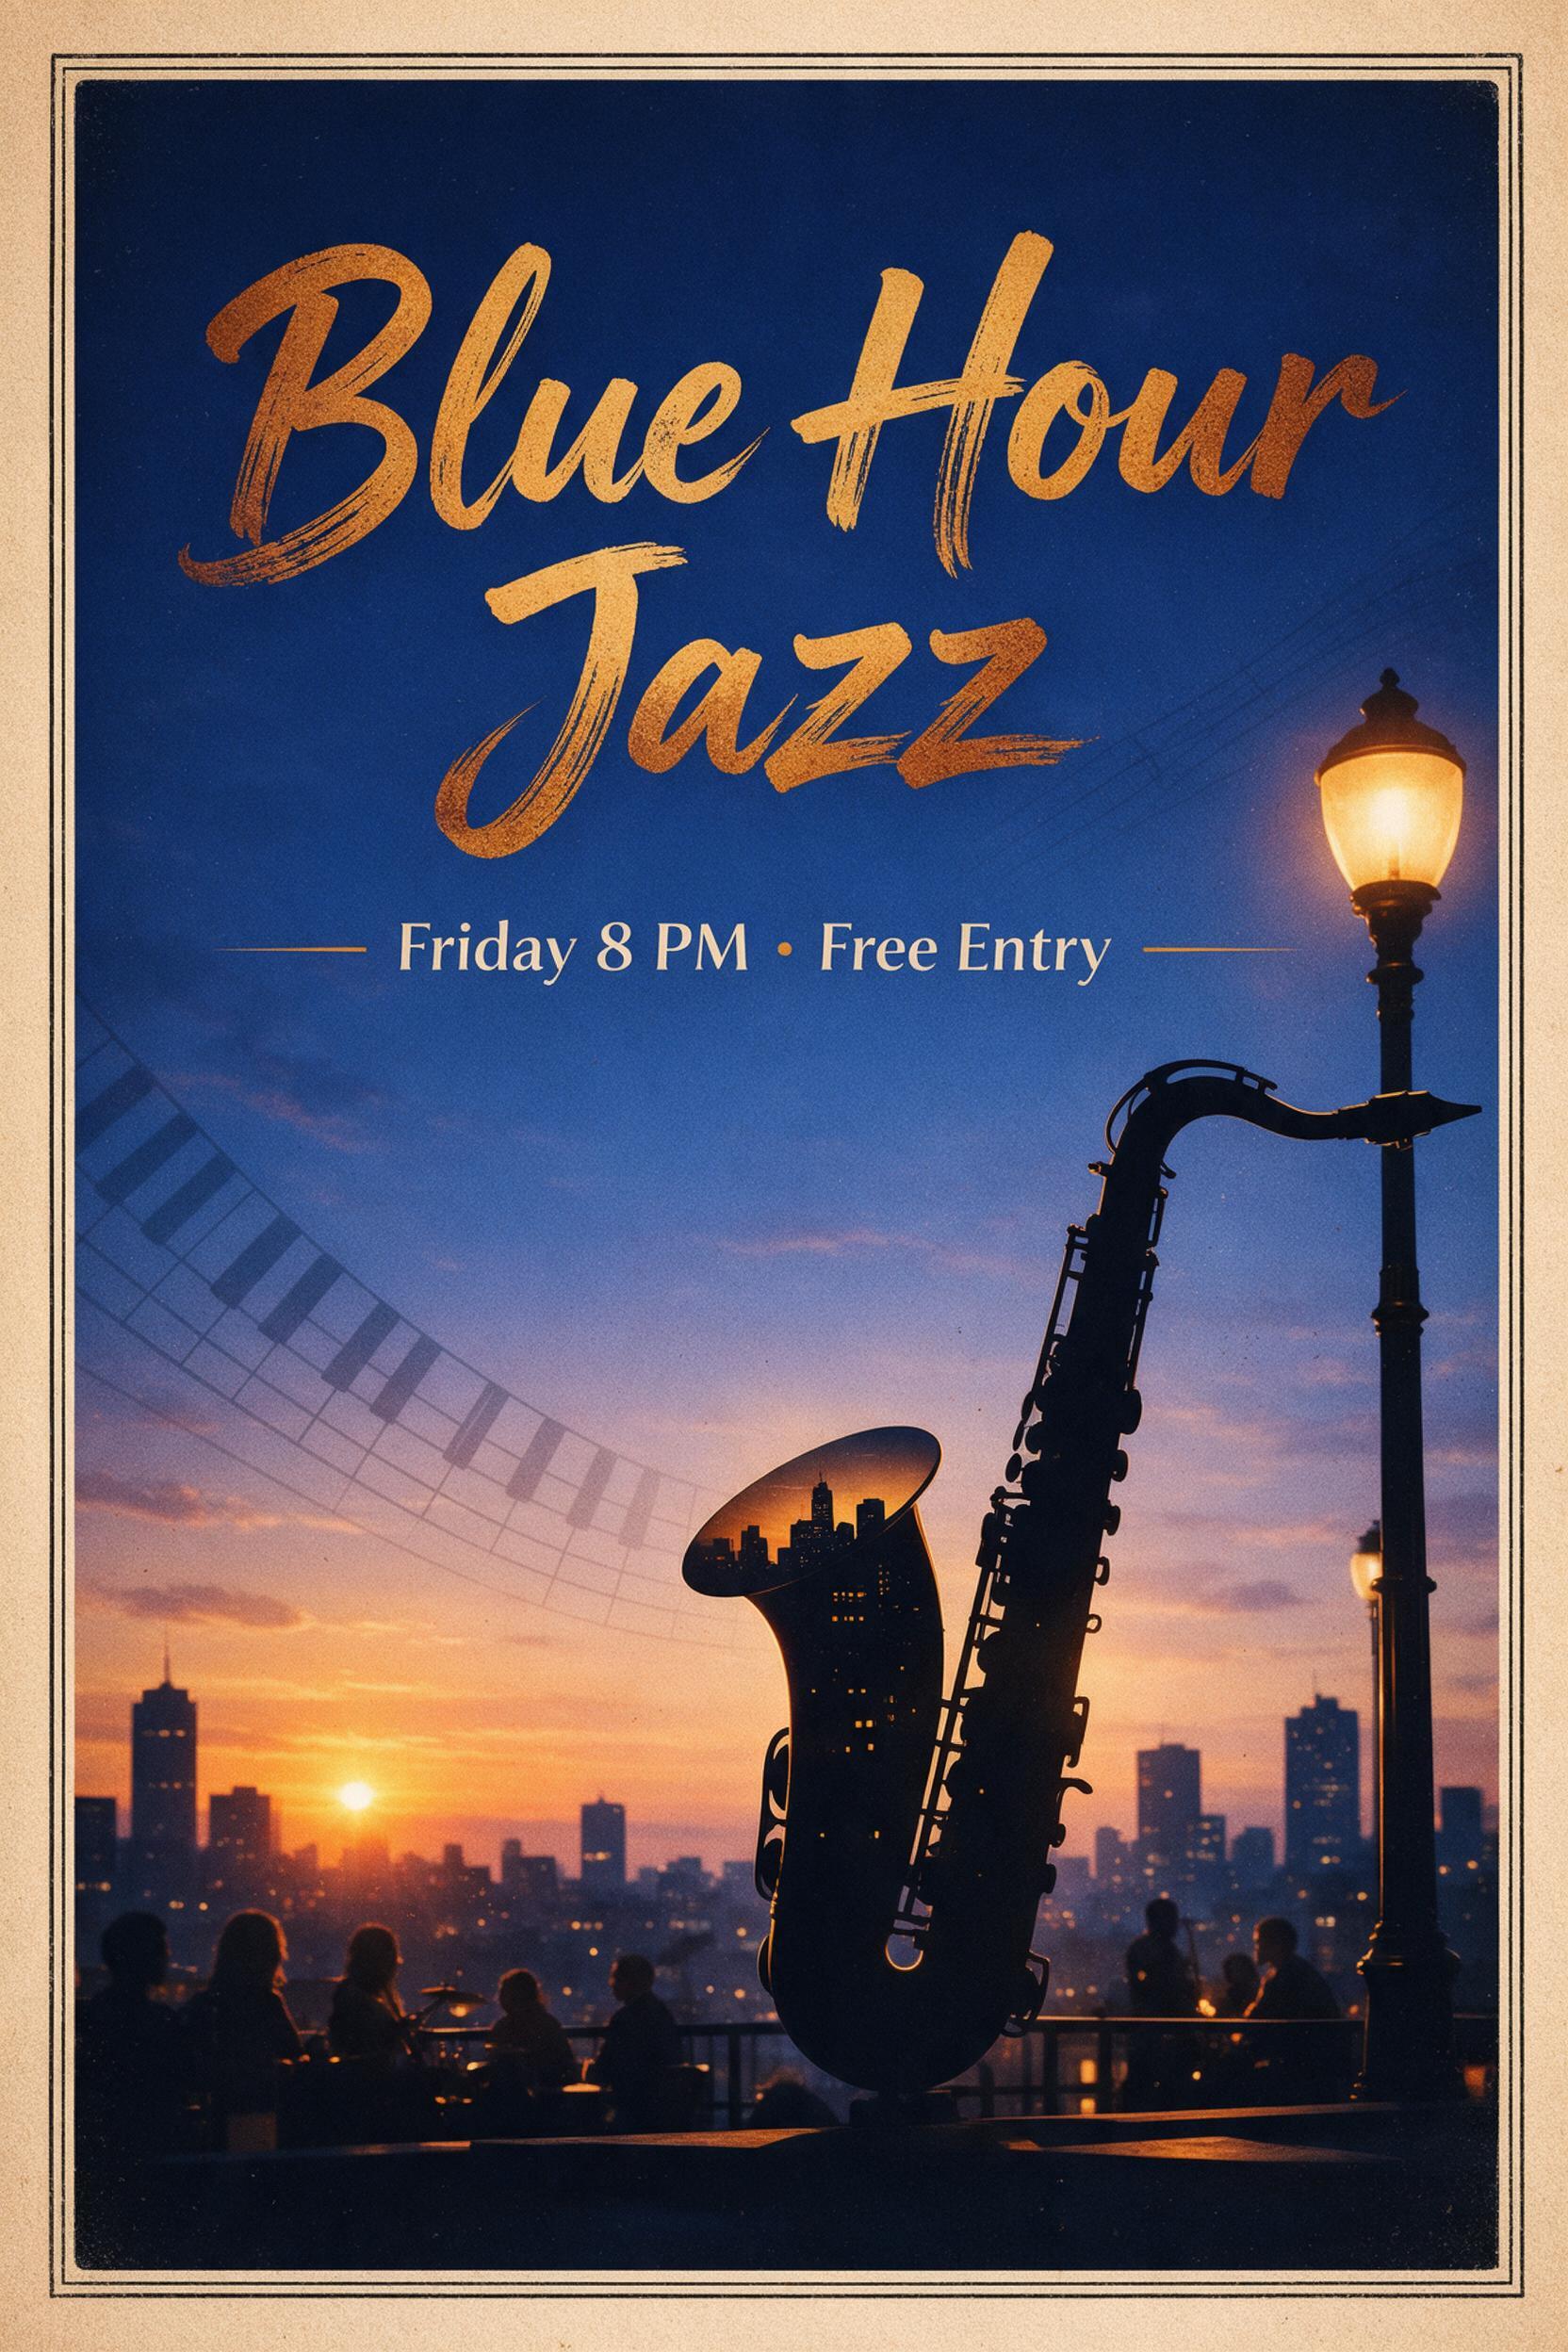
| 1Poster for a jazz night. Headline: "Blue Hour Jazz". Line below it: "Friday 8 PM · Free Entry". Warm dusk colours, a saxophone silhouette. | Passed15.8 s | Failed8.5 s | Passed1 m 12 s |
| 2Chalkboard menu outside a small coffee shop, listing exactly three items: "Flat White $4.50", "Oat Latte $5.00", "Cold Brew $4.00". Hand-drawn chalk lettering. | Passed21.1 s | Passed9.2 s | Failed1 m 12 s |
| 3Phone splash screen for a meditation app called "Stillwater", with the tagline "Breathe in. Slow down." Calm lake at dawn, lots of empty space. | Passed14.0 s | Passed9.1 s | Passed1 m 3 s |
Quality against cost
Higher and further left is better.
- Nothing else is both better and cheaper
| Contestant | Outputs passed by the model judge | Cost per call | Average response time | On the frontier |
|---|---|---|---|---|
| A · GPT Image 2.5 Sunburst | 100% | $0.0128 | 17.0 s | Yes |
| B · Nano Banana 2 (Gemini 3.1 Flash Image) | 67% | $0.0672 | 8.9 s | No |
| C · Seedream 5.0 Pro | 67% | $0.045 | 1 m 9 s | No |
Cost is the average for one call in this run. A gold ring marks a model that no other model beats on both quality and cost.
Outputs side by side
What each model returned for test case 1.
Test casePoster for a jazz night. Headline: "Blue Hour Jazz". Line below it: "Friday 8 PM · Free Entry". Warm dusk colours, a saxophone silhouette.
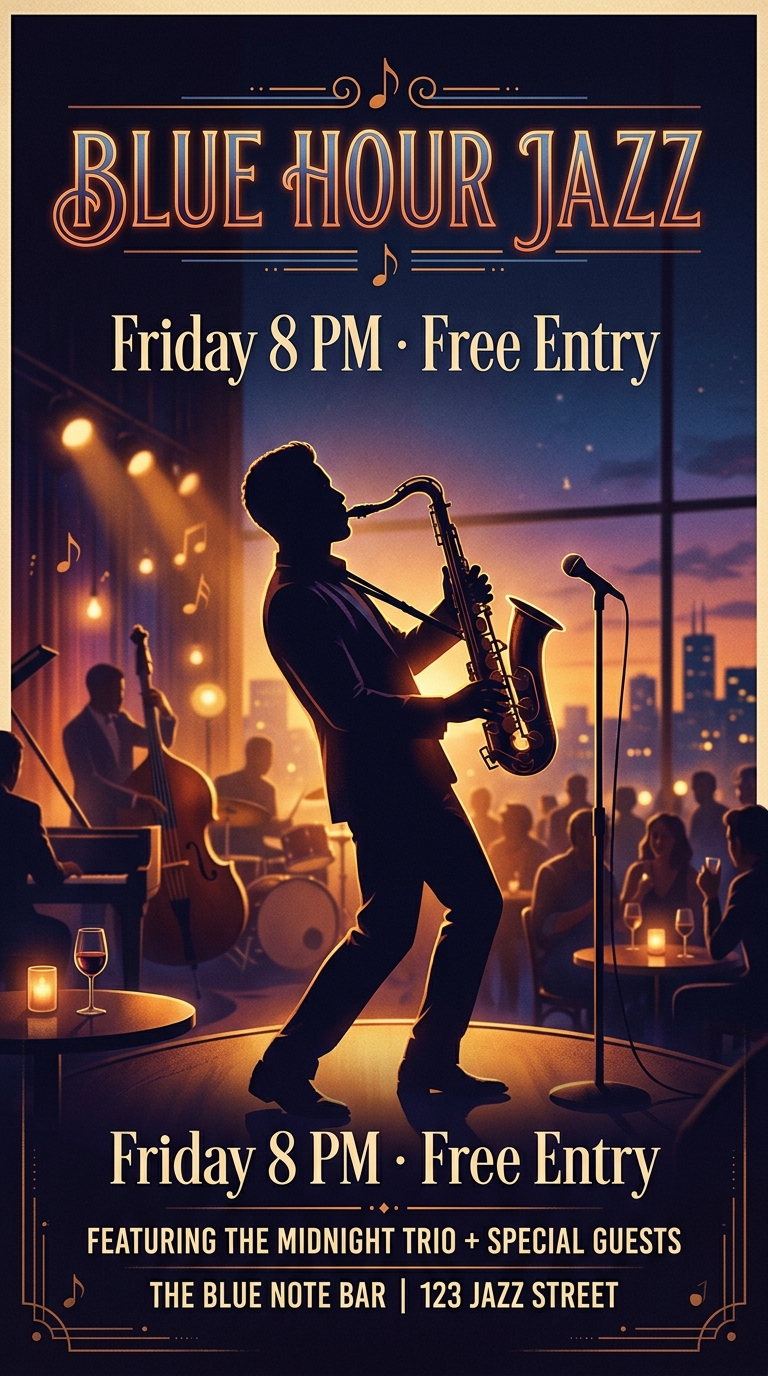
Judge's reasonThe poster includes extra, invented text at the bottom that was not specified in the prompt.
How to compare AI models with LLMCompare
Add your test cases
Type them, paste them one per line, or upload a spreadsheet. Add the expected result when you have one.
Pick the models
Choose the models and set their parameters. To test a prompt change, add a second version of the system prompt.
Read the results
Check the matrix, compare outputs side by side, review them blind, then share the report.
What people compare models for
- Switching to a cheaper model
Run your real inputs through both models and see how much quality changes for the money saved.
Start from an example - Testing a newly released model
Add the new model to an evaluation you already ran and compare it with the models you use now.
Start from an example - Choosing a model for a client
Compare the candidates on the client's own cases and send a report the client can open without an account.
Start from an example - Comparing image generation models
Give several image models the same prompts and review the images side by side.
Report
Latest model comparisons
All model comparison articles- How to run a model comparison you can trust
Ten rules from three rounds of model tests we ran by hand in August 2026, and the mistakes that produced them.
Method
Models and prices
LLMCompare calculates cost from each provider's published price. Every price shows the date it was last checked.
LLMCompare lists 443 models from 65 providers as of 18 November 2026.
See all models and prices| Model | Input | Output | Cached input |
|---|---|---|---|
| GPT-6 LunaOpenAI | $0.10 | $0.50 | $0.01 |
| Gemini 3.7 FlashGoogle | $0.75 | $3.75 | $0.075 |
| GPT-5.6 TerraOpenAI | $2.00 | $12.00 | $0.20 |
| Claude Sonnet 5Anthropic | $2.00 | $10.00 | $0.20 |
| Model | Per image | Image output, per million tokens |
|---|---|---|
| GPT Image 2.5 SunburstOpenAI | Does not apply | $30.00 |
| GPT Image 2.5 FlareOpenAI | Does not apply | $30.00 |
| Seedream 5.0 LiteByteDance Seed | $0.035 | Does not apply |
LLMCompare plans and credits
LLMCompare charges credits for the model calls in a run. The estimated credits are shown before a run starts, and a call that does not complete is not charged.
See all plans and credit prices| Plan | Price | Credits | Test cases per evaluation | Calls per run |
|---|---|---|---|---|
| Free | Free | 50 a day, up to 500 a month | 20 | 100 |
| Starter | $10.00one-time | 10,000, no expiry | 200 | 1,000 |
| Growth | $29.00per month | 32,000 every month | 500 | 3,000 |
| Expert | $99.00per month | 120,000 every month | No limit | 10,000 |
What LLMCompare does
- LLMCompare is a web tool for comparing AI models on test cases that you supply.
- LLMCompare sends each test case to every model you select and records the output, the token usage, the cost in US dollars and the response time of every call.
- LLMCompare compares text models and image generation models. Video generation models are planned.
- LLMCompare measures quality in three ways: rule checks, human review and scoring by a judge model. The three results are reported separately and are never merged into a single score.
- Human review in LLMCompare is blind by default: model names are hidden and the outputs are shuffled until you reveal them.
- LLMCompare calculates cost from each provider's published price. Every price shows the date it was last checked.
- LLMCompare needs no code and no API keys. LLMCompare calls the models for you and charges credits for the usage.
- LLMCompare does not switch to another model when a call fails. A timeout, a refusal or an empty response is recorded as that model's result.
- LLMCompare lists 443 models from 65 providers as of 18 November 2026. 11 of them can be run in an evaluation.
What LLMCompare is not
- LLMCompare is not a public leaderboard. LLMCompare does not rank models on general benchmarks.
- LLMCompare is not a chat interface.
- LLMCompare is not a production monitoring service. LLMCompare is used before launch, to choose a model.
- LLMCompare is not owned by a model provider.
Questions about comparing AI models
- How is LLMCompare different from a model leaderboard?
- A leaderboard ranks models on general benchmarks that are the same for everyone. LLMCompare runs the test cases you supply, so the results describe how each model handles your task.
- Do I need my own API keys?
- No. LLMCompare calls the models with its own accounts and charges credits for the usage.
- Which models can I compare?
- LLMCompare supports text models and image generation models. The models page lists every supported model with its price and the date the price was checked. See all models and prices
- How does LLMCompare calculate cost?
- LLMCompare multiplies the usage reported by the provider by the provider's published price on the day of the run. Reasoning tokens are included because providers bill them as output.
- Can I compare different versions of a prompt?
- Yes. Add a second version of the system prompt and LLMCompare runs the same test cases with each version.
- What happens when a model refuses a request or times out?
- LLMCompare records the refusal or timeout as that model's result for the test case. LLMCompare does not retry with another model.
- Are my test cases private?
- Yes. An evaluation is visible only to you until you share it. When you share or publish a report, all of its test cases and outputs become visible to the people who can open it.
- Can I share the results?
- Yes. You can create a link that anyone with the link can open, or publish the report. People who open a shared report do not need an account.
- How do I judge which output is better?
- LLMCompare offers three methods: rule checks such as valid JSON or required keywords, blind human review, and scoring by a judge model that follows criteria you write.